 ExtractFox
A real run
The paper below is made up, but its reference list isn't: six real, well-known works, cited the way a thesis often cites them, some in APA and some in IEEE style, five with a DOI printed and one without. We ran it through this page on September 25, 2026 with "All citations" and then asked the same API for BibTeX and RIS.
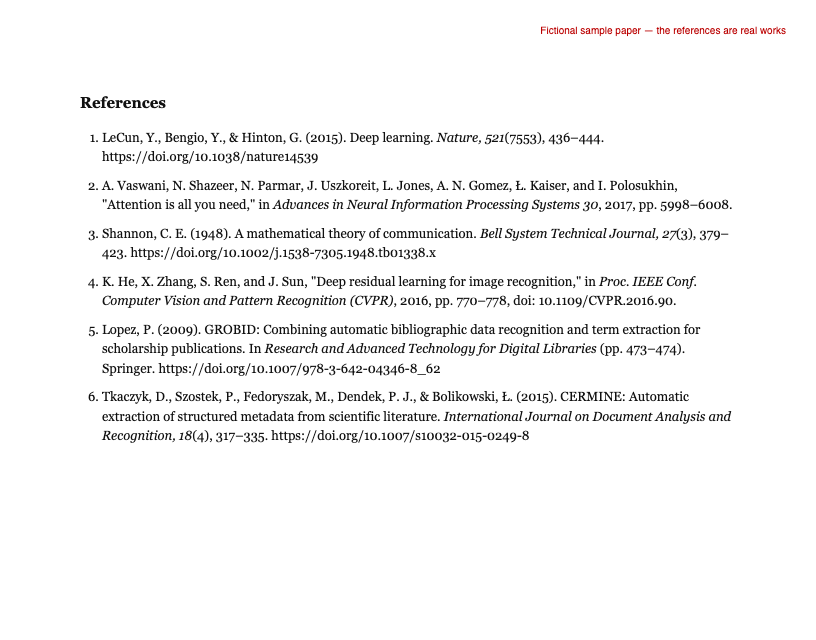
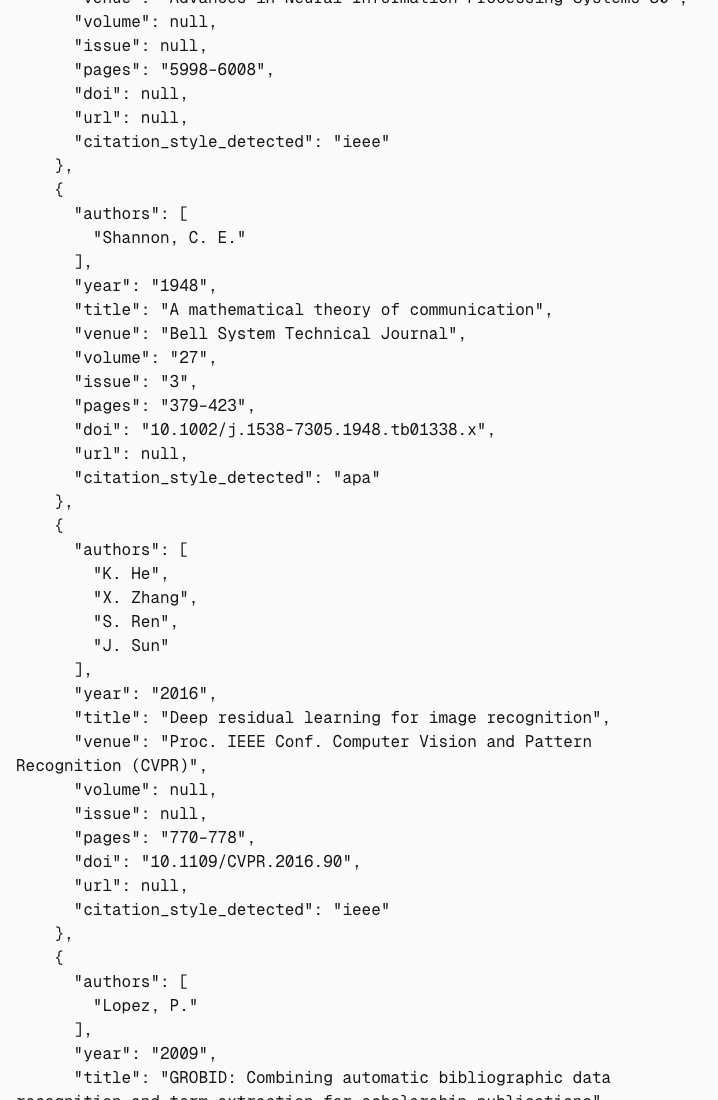
What came back for each entry.
| # | First author | Year | Style detected | DOI |
|---|---|---|---|---|
| 1 | LeCun et al. | 2015 | APA | 10.1038/nature14539 |
| 2 | A. Vaswani et al. | 2017 | IEEE | none printed → null |
| 3 | Shannon | 1948 | APA | 10.1002/j.1538-7305.1948.tb01338.x |
| 4 | K. He et al. | 2016 | IEEE | 10.1109/CVPR.2016.90 |
| 5 | Lopez | 2009 | APA | 10.1007/978-3-642-04346-8_62 |
| 6 | Tkaczyk et al. | 2015 | APA | 10.1007/s10032-015-0249-8 |
All six entries came back with the right authors, year, title, venue and page range, and each was labelled with the style it was actually written in. The entry without a printed DOI (Vaswani et al.) returned null rather than a DOI looked up or guessed: this page reads what's on the page and doesn't query Crossref.
@article{lecun2015deep,
  author = {LeCun, Y. and Bengio, Y. and Hinton, G.},
  title = {Deep learning},
  journal = {Nature},
  year = {2015},
  volume = {521},
  number = {7553},
  pages = {436--444},
  doi = {10.1038/nature14539},
  url = {https://doi.org/10.1038/nature14539}
}

@inproceedings{vaswani2017attention,
  author = {Vaswani, A. and Shazeer, N. and Parmar, N. and Uszkoreit, J. and Jones, L. and Gomez, A. N. and Kaiser, Ł. and Polosukhin, I.},
  title = {Attention is all you need},
  booktitle = {Advances in Neural Information Processing Systems 30},
  year = {2017},
  pages = {5998--6008}
}- Sample paper (PDF, fictional text, real references)
- BibTeX (.bib)
- RIS (.ris), for EndNote, Zotero and Mendeley
- CSV (the JSON flattened to one row per reference)
- JSON as returned
Extract references from a PDF
- Drop the paper, thesis or report above. The whole PDF is read, so you don't need to cut out the bibliography.
- Pick the output: All citations for JSON or a spreadsheet, BibTeX for LaTeX, CSL JSON for Zotero or Mendeley, In-text markers mapped to tie every (Smith, 2023) or [14] to its entry, or Legal citations for briefs.
- Download. For RIS, type "as RIS" in the box above the extract button; the run above did exactly that.
- Spot-check entries without a DOI before you rely on them: those are the ones no identifier can confirm.
That makes this page a reference extractor in the plain sense: PDF in, one structured record per reference out, whatever mix of styles the author used.
DOIs and citation styles
DOIs are captured when they're printed, whether as a https://doi.org/ link (APA) or a doi: suffix (IEEE); both forms in the run above came back as the bare 10.xxxx identifier. Page ranges are kept as printed; BibTeX output converts the dash to LaTeX's double hyphen.
Each entry gets a detected style: APA, MLA, Chicago, IEEE, Vancouver, Bluebook or other. The run above tests APA and IEEE in one list; we haven't published a test of the others yet, so treat those labels as a hint and check a few.
Other tools for references
| Tool | What it does with a PDF | How you run it |
|---|---|---|
| Zotero (Retrieve Metadata for PDF) | Builds a record for the PDF itself from its first pages, with Crossref, DOI and ISBN lookups. Its documentation doesn't describe extracting the reference list. | Desktop app, free |
| GROBID | Extracts and parses the whole bibliography into TEI XML; reports about .87 F1 on 1,943 PubMed Central PDFs (90,125 references). | Self-hosted Java service or Docker, Apache 2.0 |
| Crossref pdfextract | Found references in journal-article PDFs for DOI matching. Retired; Crossref points to CERMINE instead. Never handled scanned pages. | Linux, command line; no longer maintained |
| CERMINE | Extracts article metadata and the bibliography (Tkaczyk et al., 2015). | Self-hosted Java |
| This page | Reads the reference list and returns JSON, BibTeX, RIS, CSL JSON or CSV, with the style per entry. | Browser or REST API, nothing to install |
If you're processing a whole repository of papers and can run a server, GROBID is the proven choice and its accuracy is published. If you have a handful of PDFs, a thesis with mixed styles, or no server, this page is quicker.
Sources
- Zotero: Retrieve PDF metadata, checked September 25, 2026
- GROBID documentation: Introduction, checked September 25, 2026
- Crossref Labs: pdfextract, checked September 25, 2026
- Run above: this page, September 25, 2026; see how we test