 ExtractFox
Two real PDFs, start to finish
We made two PDFs of the kind that end up in Excel: a quarterly report with two tables on one page, exported from a word processor with a text layer, and an expense report that is only a picture of a page, with no text to select. Each went through this page with "All tables", and we downloaded the .xlsx it produced. Every cell was compared with the table we typed. Nothing below was edited; the PDFs and workbooks are downloadable after the results.
1. A report with two tables and negatives in parentheses
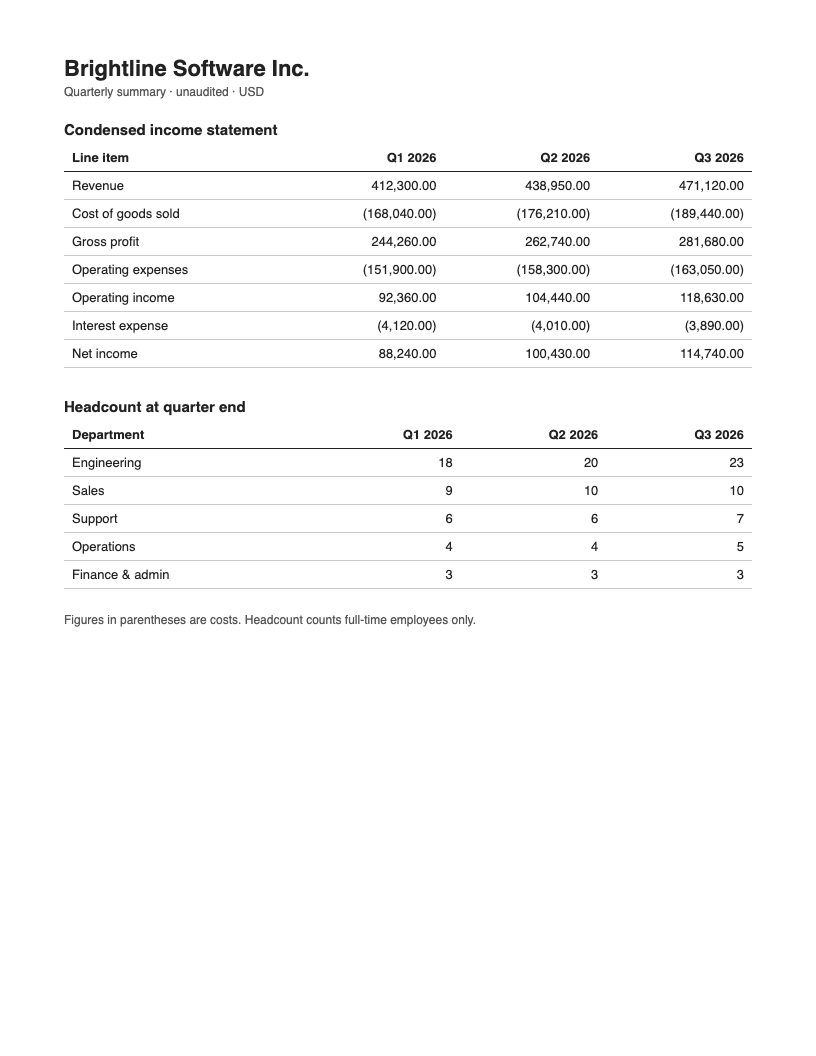
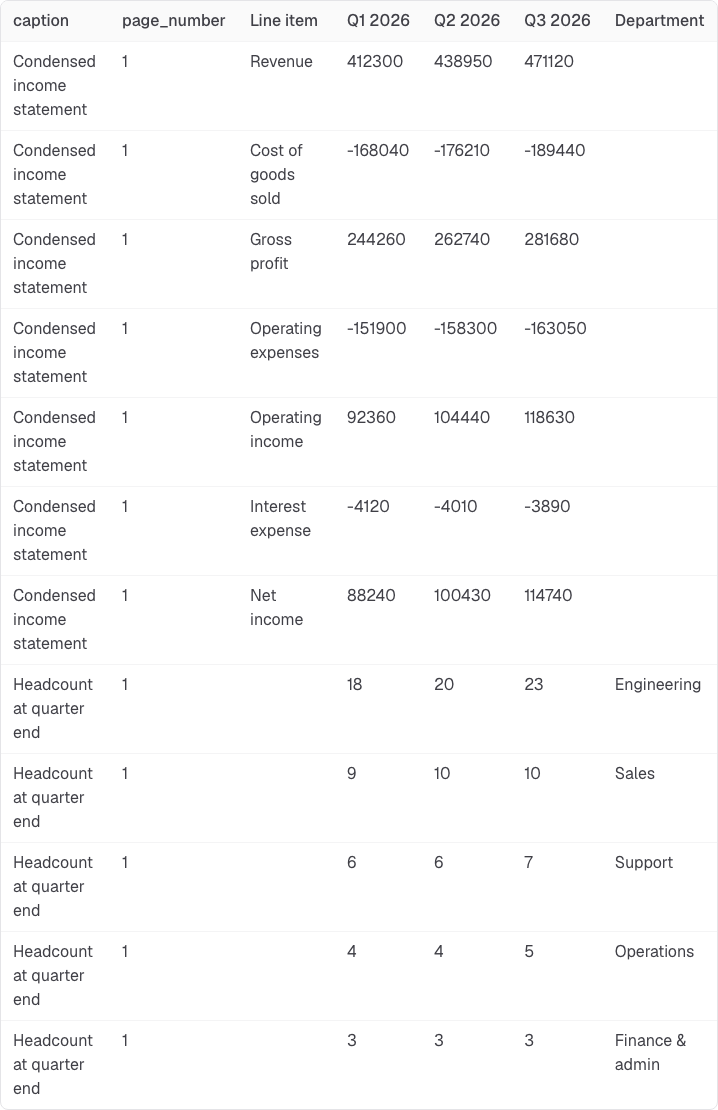
The workbook has one sheet per table, named after the heading above it: "Condensed income statement" and "Headcount at quarter end". All 36 figures are number cells; the row labels stay text. (168,040.00) became -168040, so =SUM over the quarter's Revenue, Cost of goods sold, Operating expenses and Interest expense gives the Net income printed on the page.
2. A scanned expense report
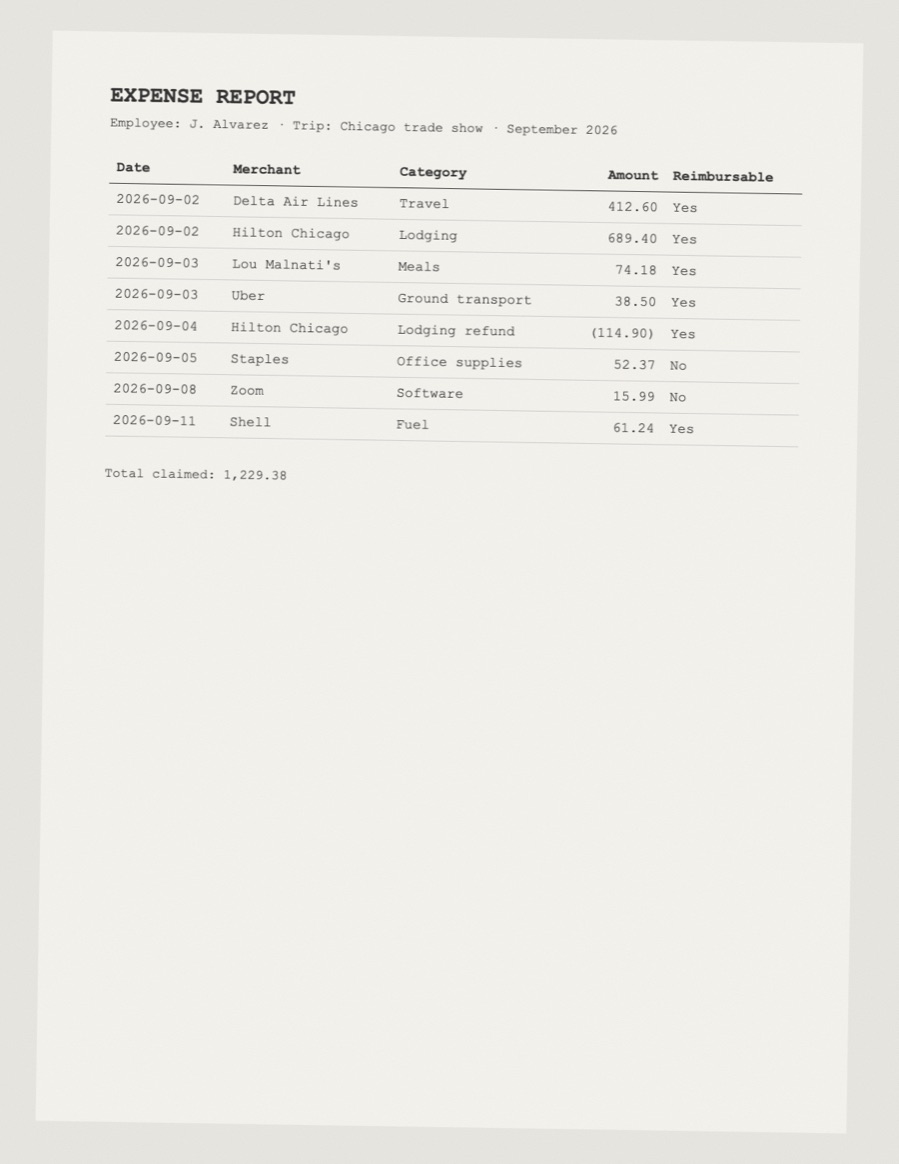
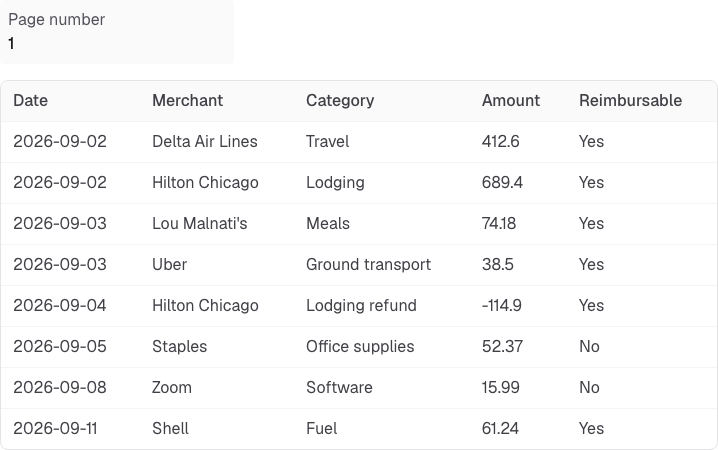
Amount is a number column with the refund as -114.9, so the column sums to 1,229.38, the "Total claimed" line under the table. That line stayed out of the rows because it is a summary, not an expense. Dates came back as 2026-09-02, which Excel reads as a date.
- Quarterly report (PDF)
- Quarterly report, Excel result
- Scanned expense report (PDF)
- Expense report, Excel result
- Scores for both cases (JSON)
Results side by side
Cells right = the value in the right row and column, compared with the table we typed. pdftotext and Tesseract return lines of text with no columns, so for them we counted how many of the true values appear anywhere in their output, which flatters them.
| Cells | ExtractFox: cells right | Number cells in the .xlsx | Seconds | Text tool: values found | |
|---|---|---|---|---|---|
| Quarterly report (text layer) | 48 | 48 | 36 (every figure), on 2 sheets | 4.4 | pdftotext: 48 |
| Expense report (image only) | 40 | 40 | 8 (Amount) | 4.7 | Tesseract: 40 |
Two PDFs is a demonstration, not a benchmark. Both were legible, one page, and laid out as plain grids. Where it gets harder: scans at low resolution where 8 and 3 look alike, tables with merged header cells spanning two levels, and very long statements. A cell that can't be read comes back empty rather than guessed, so check for blanks before you trust a total.
Why copy and paste from a PDF doesn't give you columns
When a PDF has a text layer, its text can be read (this is what pdftotext does, and roughly what you get when you select and copy). It found every value of the quarterly report. What it returns is lines, with columns lined up by spaces (below). Paste that into Excel and each line lands in one cell of column A. Text to Columns can split it, but the item names have spaces in them, and the figures stay text until you strip the commas and turn the parentheses into minus signs. The scanned expense report has no text layer at all, so there is nothing to copy.
Condensed income statement
 Line item                                                 Q1 2026                Q2 2026            Q3 2026
 Revenue                                                412,300.00              438,950.00         471,120.00
 Cost of goods sold                                    (168,040.00)            (176,210.00)       (189,440.00)
 Gross profit                                           244,260.00              262,740.00         281,680.00
On the scan, Tesseract found all 40 values as text, plus stray characters where the page had marks ("2026-09-02 = Hilton Chicago"). It, too, returns lines, not cells.
Excel's own Get Data From PDF
Excel can import PDF tables itself: Data > Get Data > From File > From PDF, pick the file, and the Navigator lists the tables it found so you can load one or several. Microsoft lists it for Microsoft 365, Excel 2024, 2021, 2019 and 2016, and it needs the .NET Framework 4.5 or later. It reads the text inside the PDF; Microsoft's page says nothing about scans, and an image-only PDF has no text for it to find. If your PDF has a text layer and you already have Excel, try it first, it costs nothing extra. This page also reads image-only scans and phone photos saved as PDF, works in any browser, turns (1,234.00) into -1234 as a number, and takes a plain-English filter such as "only rows where Amount is over 500".
Getting a clean result
- Keep "Everything" when you want the tables exactly as printed. Use "Line items" or a description in the box when you want your own columns, for example "date, vendor and total for every invoice line".
- A table that continues on the next page comes back as one table, with the repeated header dropped.
- Part numbers and codes that start with 0 stay text, so 004512 doesn't become 4512.
- For many PDFs, select them together (up to 25 per batch with a plan or a credit pack). They come back as one sheet with a source_file column.
- Need the same thing for a program? PDF to CSV gives a UTF-8 CSV and PDF to JSON the raw structure.
Sources
- pdftotext 26.10.0 (Poppler) run as pdftotext -layout file.pdf -, October 14, 2026
- Tesseract 5.5.3 run as tesseract page.png - --psm 6 on the scanned page, October 14, 2026
- Microsoft Support, "Import data from data sources (Power Query)", section From PDF (support.microsoft.com), checked October 14, 2026
- ExtractFox runs on the same PDFs, October 14, 2026; script in the repo at scripts/samples/pdf-tables.mjs, method on how we test