 ExtractFox
Three real tests
We wrote three pieces of code, turned each into the kind of picture people actually have, and ran every picture through this page and through Tesseract 5.5.3, the open-source OCR engine most free tools are built on. Nothing below was edited. The pictures, the true source and both outputs are downloadable at the end of this section.
1. A paused video tutorial (Python)
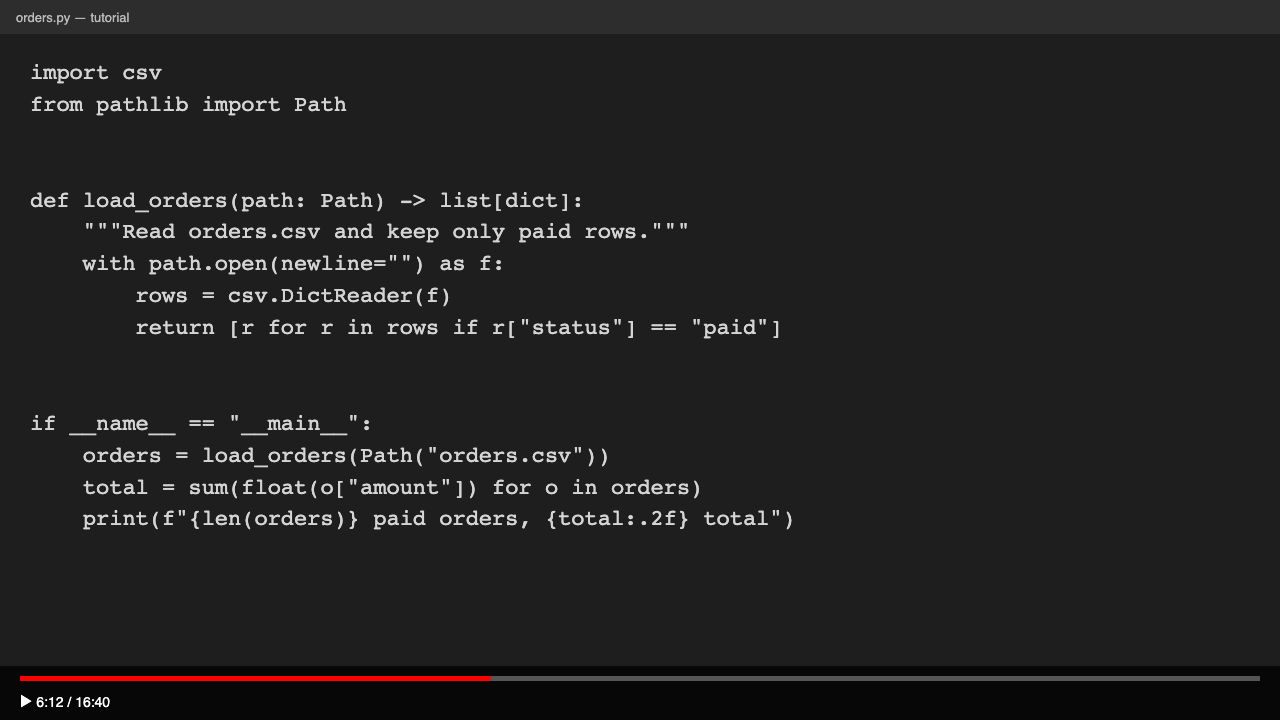
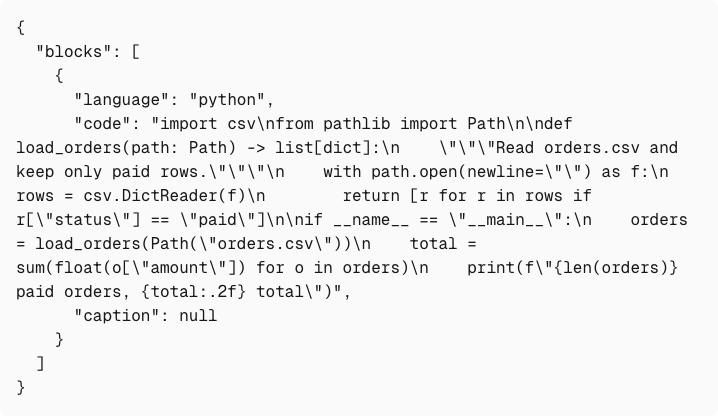
import csv
from pathlib import Path


def load_orders(path: Path) -> list[dict]:
    """Read orders.csv and keep only paid rows."""
    with path.open(newline="") as f:
        rows = csv.DictReader(f)
        return [r for r in rows if r["status"] == "paid"]


if __name__ == "__main__":
    orders = load_orders(Path("orders.csv"))
    total = sum(float(o["amount"]) for o in orders)
print(f"{len(orders)} paid orders, {total:.2f} total")orders.py — tutorial import csv from pathlib import Path def load_orders(path: Path) -> list[dict]: """Read orders.csv and keep only paid rows.""" with path.open(newline="") as f£:
2. A conference slide on a dark background (JavaScript)
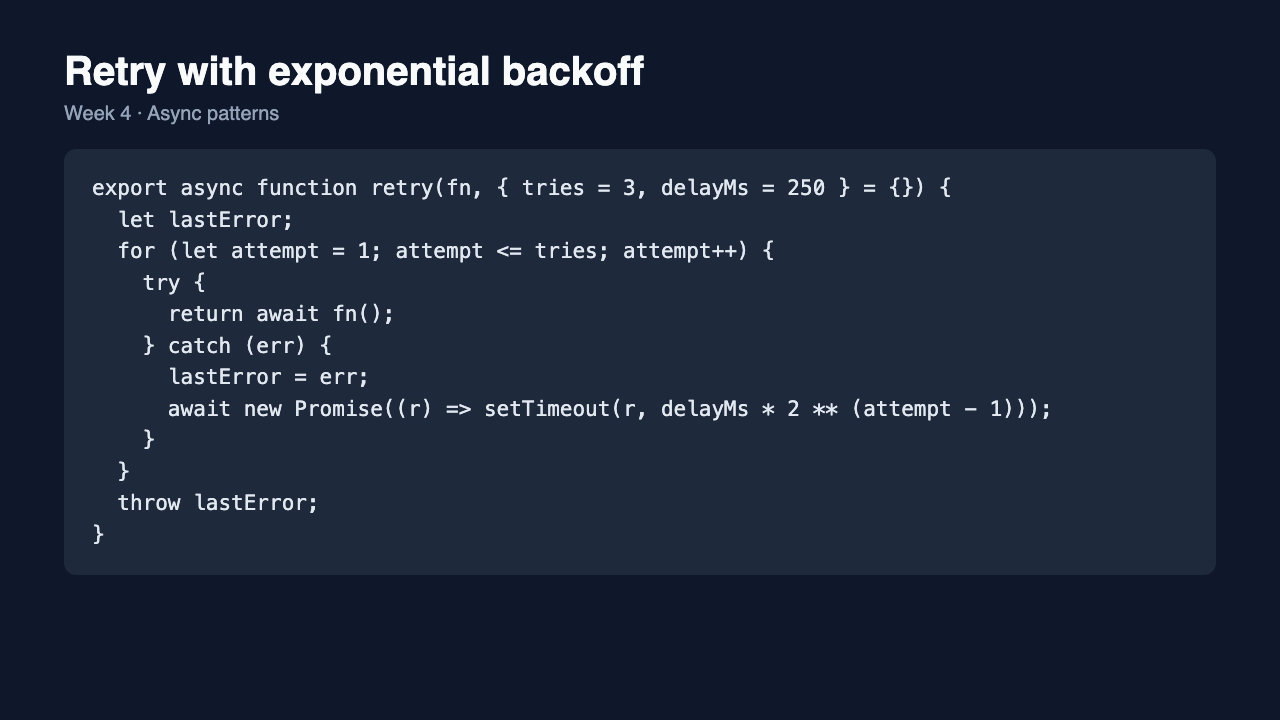
export async function retry(fn, { tries = 3, delayMs = 250 } = {}) {
  let lastError;
  for (let attempt = 1; attempt <= tries; attempt++) {
    try {
      return await fn();
    } catch (err) {
      lastError = err;
      await new Promise((r) => setTimeout(r, delayMs * 2 ** (attempt - 1)));
    }
  }
  throw lastError;
}Retry with exponential backoff
Week 4 - Async patterns
export async function retry(fn, { tries = 3, delayMs = 250 } = {}) {
let lastError;
for (let attempt = 1; attempt <= tries; attempt++) {
try {3. A phone photo of a monitor (Go)
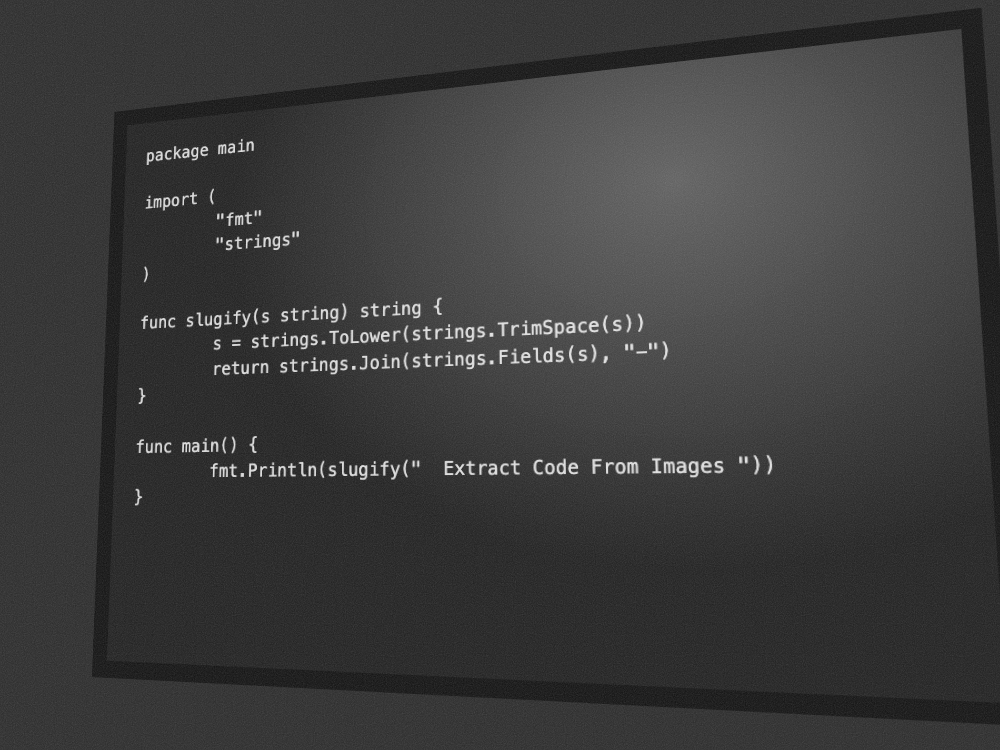
package main

import (
	"fmt"
	"strings"
)

func slugify(s string) string {
	s = strings.ToLower(strings.TrimSpace(s))
	return strings.Join(strings.Fields(s), "-")
}

func main() {
	fmt.Println(slugify("  Extract Code From Images "))
}a
package main —
"strings" uy
func slugify(s string) string { ; : 2
s = strings. ToLower(strings. Tr |
return strings.Join(strings.Fields\s? ; 2- Video frame (PNG)
- Slide (PNG)
- Phone photo (PNG)
- Scores for every case (JSON)
- Full Tesseract output, video frame
Results side by side
Errors are character edits (Levenshtein distance) from the true source after trimming trailing spaces. Tesseract has no idea what is code, so titles it read count against it; that is also what you'd have to clean up by hand.
| Picture | Characters | ExtractFox errors | Tesseract errors | Exact lines (EF) | Exact lines (Tess.) | Indent right (EF) | Indent right (Tess.) |
|---|---|---|---|---|---|---|---|
| Video frame | 444 | 0 | 84 | 15/15 | 0/15 | 15/15 | 8/15 |
| Dark slide | 326 | 0 | 96 | 12/12 | 0/12 | 12/12 | 2/12 |
| Phone photo | 235 | 0 | 58 | 15/15 | 0/15 | 15/15 | 6/15 |
Three pictures is a demonstration, not a benchmark, and all three were clean, legible code. Where this breaks: text smaller than about 9 pixels high, code cut off at the edge of the frame, and motion blur from pausing mid-scroll. In those cases the extractor returns what it can read rather than guessing at the rest, so check the last lines.
Extract code from a video
- Pause where the whole snippet is on screen. If the presenter scrolls, take one frame per screenful.
- Switch the player to full screen and the highest quality; small, compressed frames are where characters go wrong.
- Take a screenshot: Cmd+Shift+4 on a Mac, Win+Shift+S on Windows, or the screenshot button on a phone.
- Drop the picture above. For several frames, upload them together and pick "All code blocks"; each frame comes back as its own block.
- Copy the code or download it. Run it once before you trust it: a presenter's code may depend on files you don't have.
You don't need to crop the player controls, subtitles or the window title; the first test above kept them in on purpose.
Languages we tested
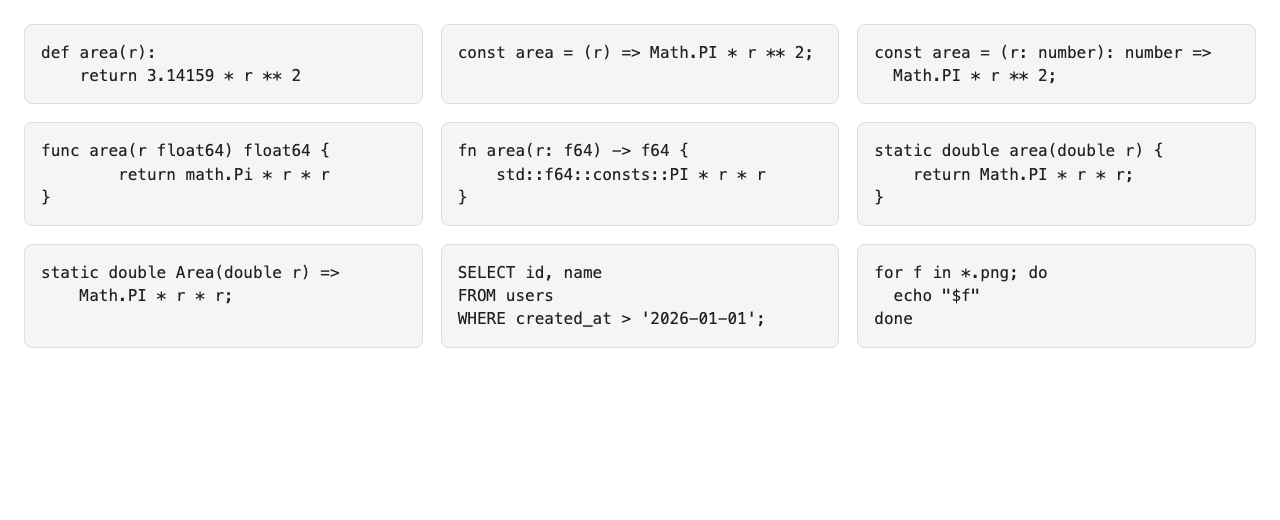
| Snippet | Language detected | Code |
|---|---|---|
| Python | python | Exact |
| JavaScript | javascript | Exact |
| TypeScript | typescript | 2 characters off: indentation width |
| Go | go | 4 characters off: indentation width |
| Rust | rust | Exact |
| Java | java | Exact |
| C# | c# | Exact |
| SQL | sql | Exact |
| Bash | bash | 2 characters off: indentation width |
Every language was named correctly. The three misses were all the same thing: indentation that was two spaces or a tab came back as four spaces. Characters and line breaks were right. If indentation width matters (Makefiles, YAML, Go formatting), say so in the box above the extract button, e.g. "keep tabs and two-space indents exactly".
When plain OCR is enough
Tesseract is free, runs offline and is very good at black text on a white page. Code is a harder case for it: indentation carries meaning, symbols like { } [ ] and => look alike at low resolution, and it has no way to tell code from the slide title or the video player around it. If your pictures are clean, high-resolution and you're happy to fix spacing by hand, it's a fine choice. If you want the code to run on the first paste, use a model that reads it as code.
Sources
- Tesseract 5.5.3 run as tesseract image.png - --psm 6 (one uniform block of text), September 25, 2026
- ExtractFox runs on the same images, September 25, 2026; script in the repo at scripts/samples/code.mjs, method on how we test