 ExtractFox
Two real PDFs, start to finish
We made two PDFs that are awkward to turn into CSV: a two-page supplier price list whose descriptions are full of commas and inch marks (1/2") and whose part numbers start with 0, and a delivery note that is only a picture of a page, with no text to select. Each went through this page with "All tables", and we downloaded the CSV. Every cell was compared with the table we typed, and the file was parsed back with a standard CSV reader. Nothing below was edited.
1. A two-page price list with commas and quotes
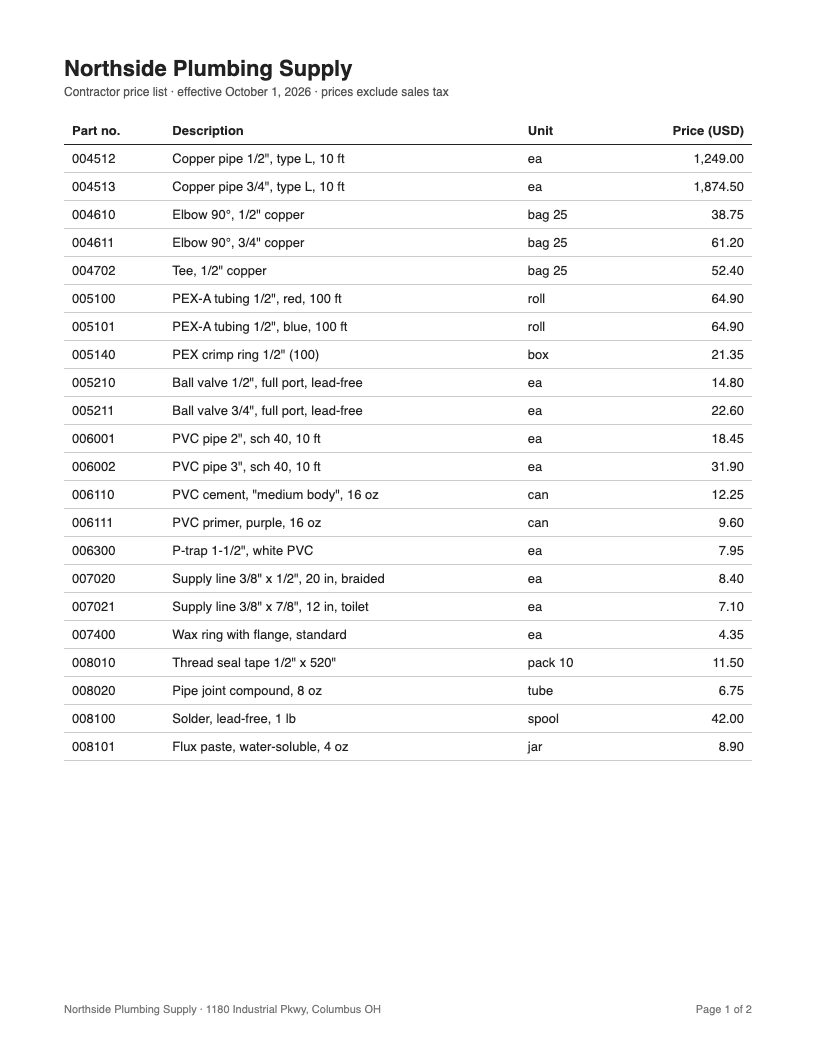
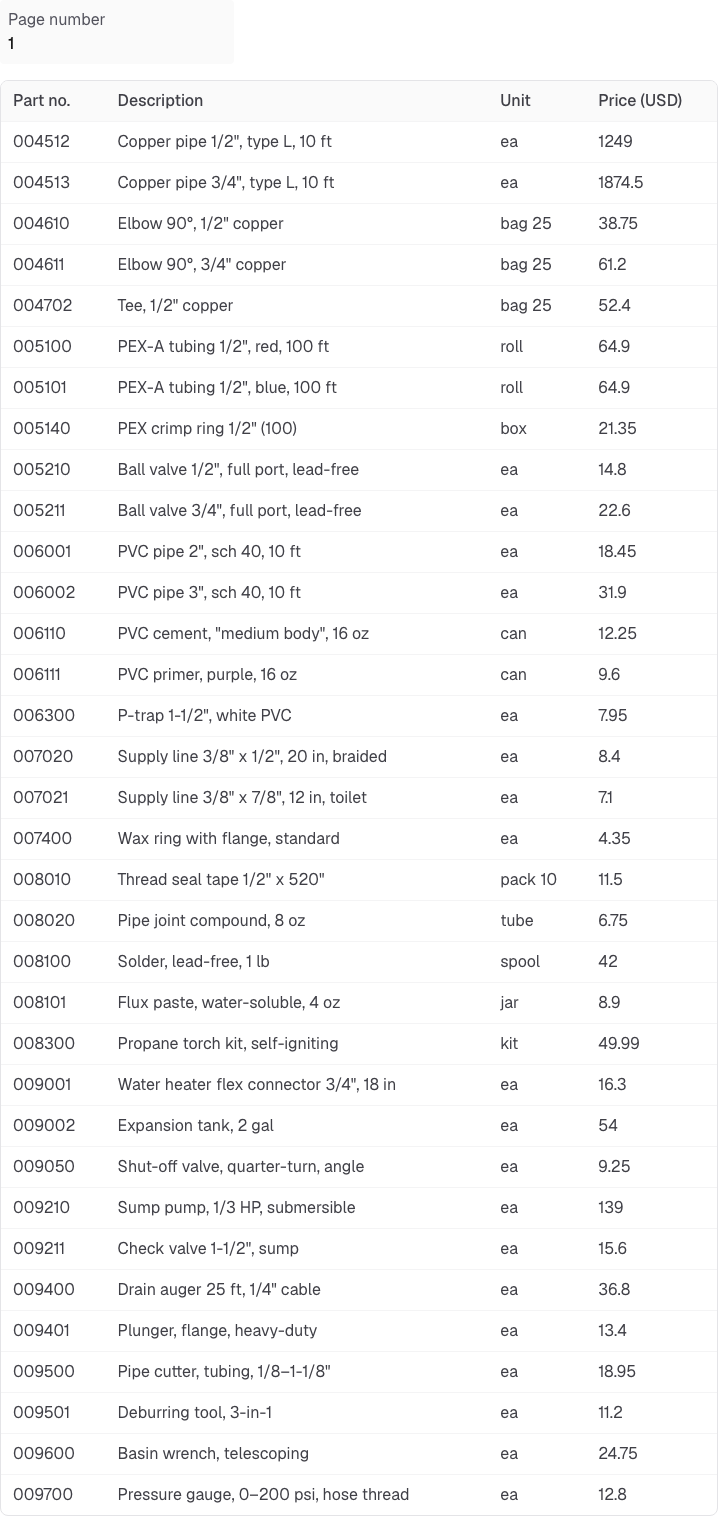
The CSV has one header and 34 rows, and every row parses to exactly 4 fields. A description such as Copper pipe 1/2", type L, 10 ft is wrapped in quotes with the inch mark doubled, so its commas stay inside the field. Part numbers stay 004512, and 1,249.00 is written as 1249 without the thousands comma that would otherwise split the column.
Part no.,Description,Unit,Price (USD)
004512,"Copper pipe 1/2"", type L, 10 ft",ea,1249
004513,"Copper pipe 3/4"", type L, 10 ft",ea,1874.5
004610,"Elbow 90°, 1/2"" copper",bag 25,38.75
2. A scanned delivery note
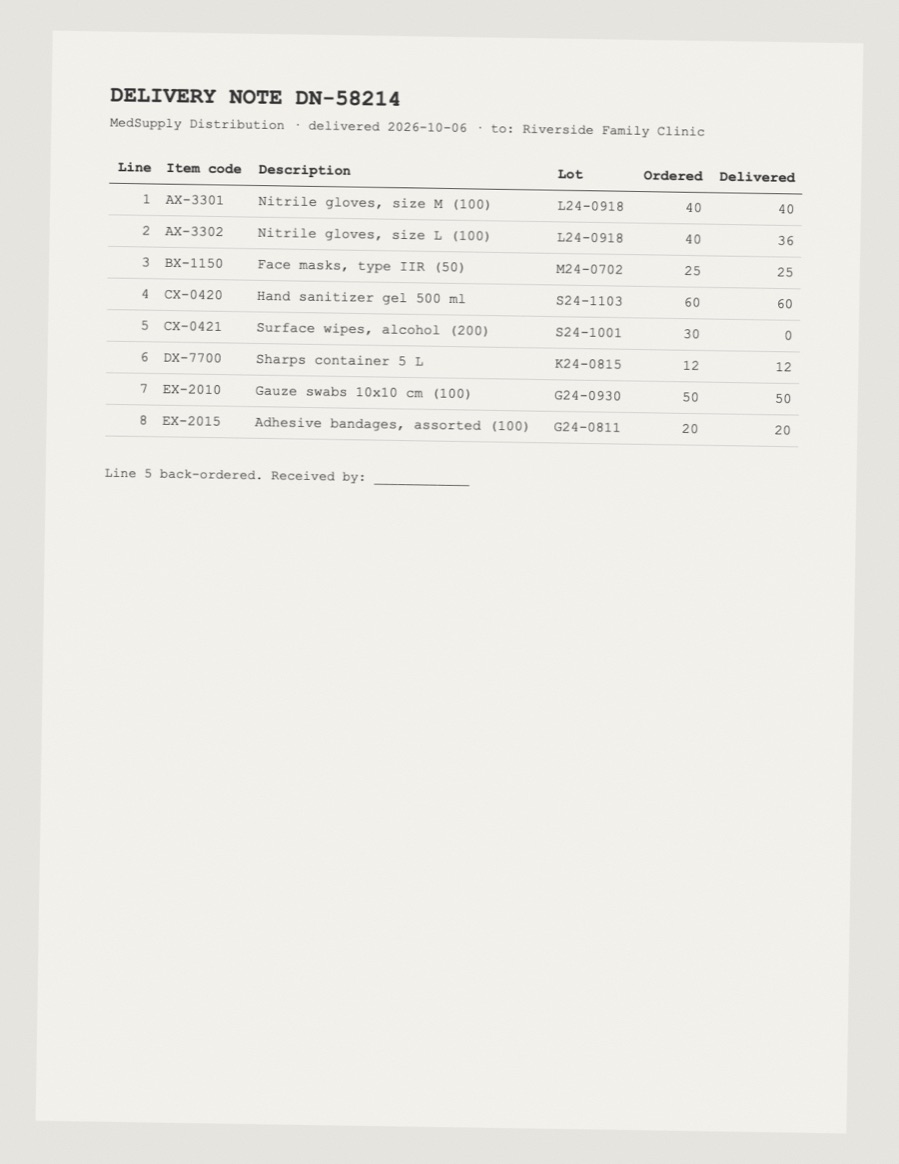
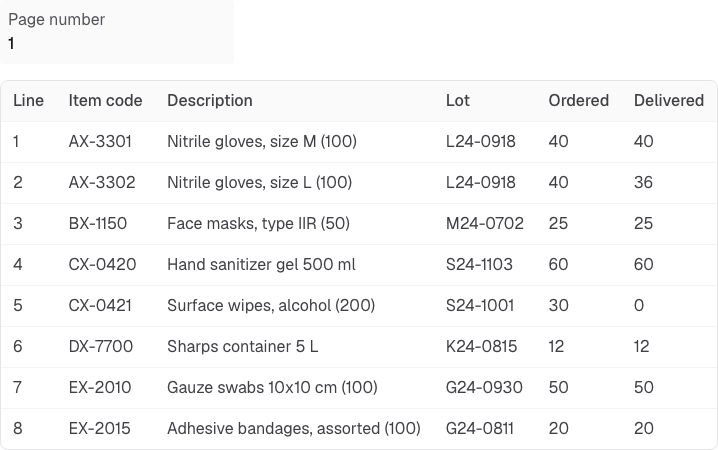
Lot numbers like L24-0918 and S24-1103 are where plain OCR slips: Tesseract read them as 124-0918, $24-1103 and 624-0930. In the CSV every lot is right, and Ordered and Delivered are plain numbers, so the back-ordered line (30 ordered, 0 delivered) is easy to filter.
- Price list (PDF, 2 pages)
- Price list, CSV result
- Scanned delivery note (PDF)
- Delivery note, CSV result
- Scores for both cases (JSON)
Results side by side
Cells right = the value in the right row and column, compared with the table we typed. pdftotext and Tesseract return lines of text with no columns, so for them we counted how many of the true values appear anywhere in their output, which flatters them.
| Cells | ExtractFox: cells right | CSV rows / fields per row | Seconds | Text tool: values found | |
|---|---|---|---|---|---|
| Price list (text layer, 2 pages) | 136 | 136 | 34 / always 4 | 6.4 | pdftotext: 136 |
| Delivery note (image only) | 48 | 48 | 8 / always 6 | 4.7 | Tesseract: 43 |
Two PDFs is a demonstration, not a benchmark. Both were legible and laid out as plain grids. Where it gets harder: low-resolution scans, headers that span two rows, and very long statements. A cell that can't be read comes back empty rather than guessed.
Why extracting the text isn't a CSV yet
pdftotext found every value in the price list, because the PDF has a text layer. It gives lines with columns lined up by spaces, and the description column itself contains spaces and commas, so splitting on either breaks rows. Saving that text as .csv gives one field per line. The scanned delivery note has no text layer, and Tesseract's lines mix up letters and digits in exactly the codes you would join on.
Line Item code Description Lot Ordered Delivered
1 AX-3301 Nitrile gloves, size M (100) 124-0918 40 40
2 AX-3302 Nitrile gloves, size L (100) 124-0918 40 36
3 BX-1150 Face masks, type IIR (50) M24-0702 25 25
4 Cx-0420 Hand sanitizer gel 500 ml $24-1103 60 60
What the CSV file looks like
- Comma-separated, CRLF line ends, one header row. A field with a comma, quote or line break is wrapped in double quotes and inner quotes are doubled (RFC 4180).
- UTF-8 with a byte-order mark, which is how Excel knows to show 90° and not 90° when you double-click the file. In Python, read it with encoding="utf-8-sig" so the first header has no stray character; pandas.read_csv(path, encoding="utf-8-sig").
- Amounts and quantities are plain numbers (1249, -114.9): no currency symbols, no thousands separators.
- A table that continues on the next page becomes one block of rows with one header. When the PDF has several tables, each row carries the table's caption and page so you can tell them apart.
- A value that starts with =, +, - or @ and is text gets a leading apostrophe, so a spreadsheet doesn't run it as a formula.
Leading zeros and Excel
The CSV keeps 004512 as written. Excel, when it opens a CSV by double-click, decides on its own that 004512 is a number and shows 4512. If the codes matter, either download .xlsx from PDF to Excel, where codes are stored as text, or import the CSV with Data > From Text/CSV and set that column to Text before loading. In Google Sheets, File > Import with "Convert text to numbers, dates, and formulas" unticked keeps them too.
Getting the CSV you need
- "Everything" (every table) keeps the PDF's own column headers. For fixed columns across many different PDFs, describe them in the box: "date, description, amount, balance" gives the same header every time.
- For many PDFs, select them together (up to 25 per batch with a plan or a credit pack): one CSV with a source_file column.
- From code, the API returns the same extraction as JSON, ready to write out as CSV.
Sources
- pdftotext 26.10.0 (Poppler) run as pdftotext -layout file.pdf -, October 14, 2026
- Tesseract 5.5.3 run as tesseract page.png - --psm 6 on the scanned page, October 14, 2026
- RFC 4180, Common Format and MIME Type for Comma-Separated Values (CSV) Files
- ExtractFox runs on the same PDFs, October 14, 2026; script in the repo at scripts/samples/pdf-tables.mjs, method on how we test